What are Snapshots?
Introduction
The snapshot mechanism was created to address a number of issues with the standard way of storing, accessing and sharing data files.
- Once created, the data is immutable, but you can alter the description.
- The snapshot is referenced by ID and not a path name. You interact with the file using ImageTank and not the Finder.
- Separates the location of data (as snapshots) and processing scripts (ImageTank files and external programs).
- You can search for snapshots based on description as well as snapshot name.
- You can easily see find every ImageTank file in your home directory that references a given snapshot.
- ImageTank implements a cloud storage mechanism, built on the S3 bucket mechanism. You can use sites such as Backblaze or AWS and S3 buckets can be hosted by research groups or university IT.
- The approach is cloud hosted and locally cached. You can make snapshots available to a local research group or allow anyone using ImageTank to download the snapshot by giving them a link. They will not be able to browse your data set.
- The file format is documented and has a easy to use open source library.
How Snapshots are stored
Snapshots are broken into two files on disk. One is the info or metadata, and has the file extension .info. This is the changeable part. The other is the data, and that ending varies. This file is not changeable and determines the name of the snapshot file pair (i.e. the name before the path extension). In fact the file name is the sha256 hash of the data file. This is a 256 bit number, encoded as a 64 character hexadecimal number. In decimals this is a 77 digit number. This is viewed as a globally unique ID for your dataset. Mathematically a collision (two different data sets with the same computed ID) is possible, but so vanishingly small that it is hard to fully understand it.
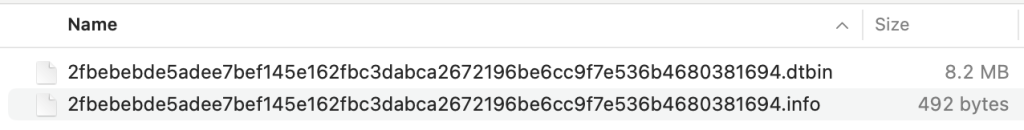
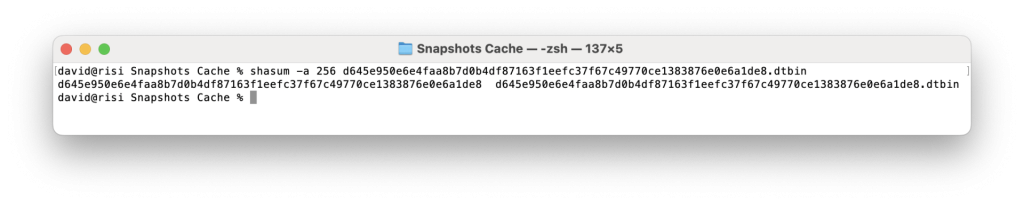
The checksum calculation is a standard alghorithm, and you can verify it using a command line utility – shasum. If the file changes the checkum changes as well.
Types of Data Files
Snapshots have different types. Some of those have a different file extension than dtbin.
- Time series of a single variable. Ending is .dtbin
- Movie file. This is a copy, no modification or recompression.
- SQLite database file – Ending is .sqlite
- A collection of variables, can be time dependent.
Create a Snapshot
Snapshots are created in ImageTank and store the state of an object. Take for example an object where you take a folder of tiff files and create a time series of images.
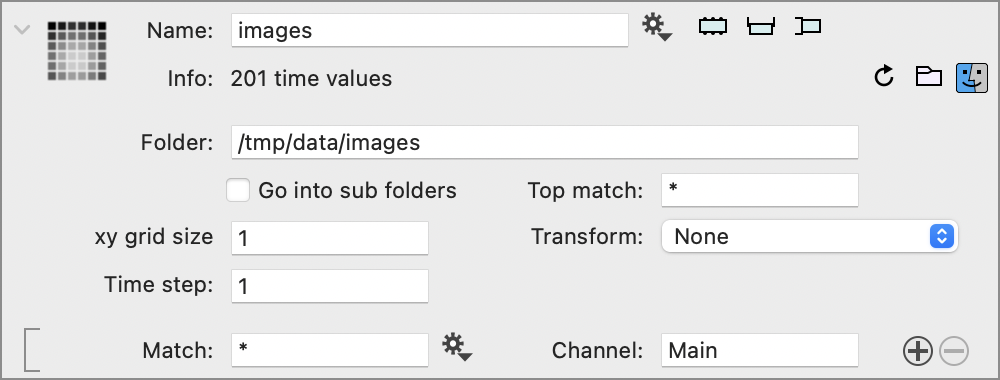
This object is only valid when there are files in the specified folder, and if you want to share this with someone else you need to send the content of that folder through some mechanism, typically a drop box link. On top of that hassle is figuring out how to archive the images, how to document what the images are of. Then make sure that you don’t accidentally delete them when you are cleaning up your machine.
You can use the snapshot mechanism to do this. In the gear menu select the ‘Take Snapshot’ entry

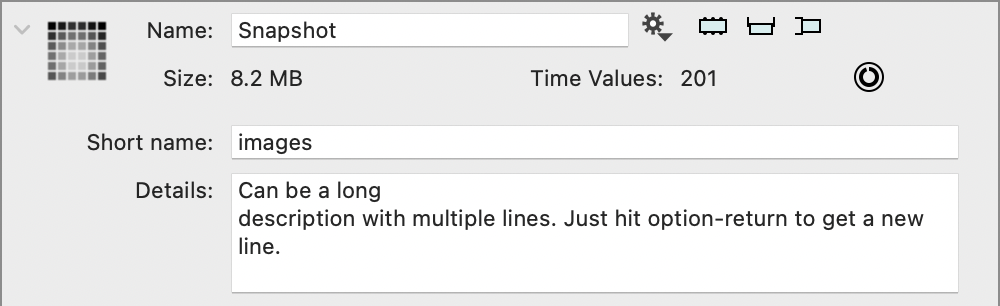
What you get is the following entry:
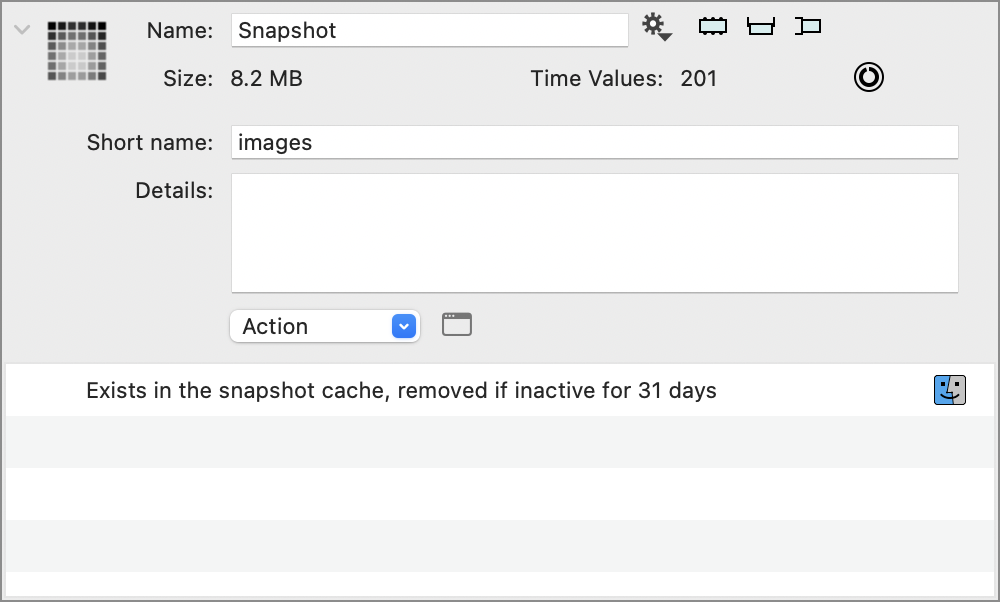
What really happened is that all 201 files were computed and saved into a single data file. If you click on the Finder icon in the table above you reveal the file. There are three files stored with the same name, different ending.
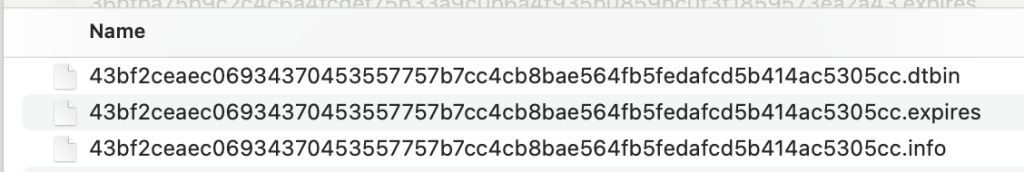
The .dtbin file is where the data is stored. The .info file is the metadata for the file. That is, it contains information about when the file was created, who created it, what it contains and both the short name and full description. The .expires is a file that is used to know when this file should be removed. Removal is discussed elsewhere.
The file name is the sha256 checksum for the file. You can verify that the file has not been changed by using the following command in the terminal:
shasum -a 256 43bf2ceaec06934370453557757b7cc4cb8bae564fb5fedafcd5b414ac5305cc.dtbinSee the wikipedia for more information about SHA checksum. The key results for the checksum is that it gives a 32 byte digest that when you write it as hex code is 64 characters. It is created such that small changes in the input cause big changes in the output and it is astronomically hard to to find or create a different file with the same checksum. This checksum can therefore be viewed as a global identifier for your data file.
Guidance
Changing Snapshots
Changing the data of the snapshot is not possible. In fact that is one of the big benefits of this approach, you know that the data hasn’t changed. The meta data however can be changed at any time.
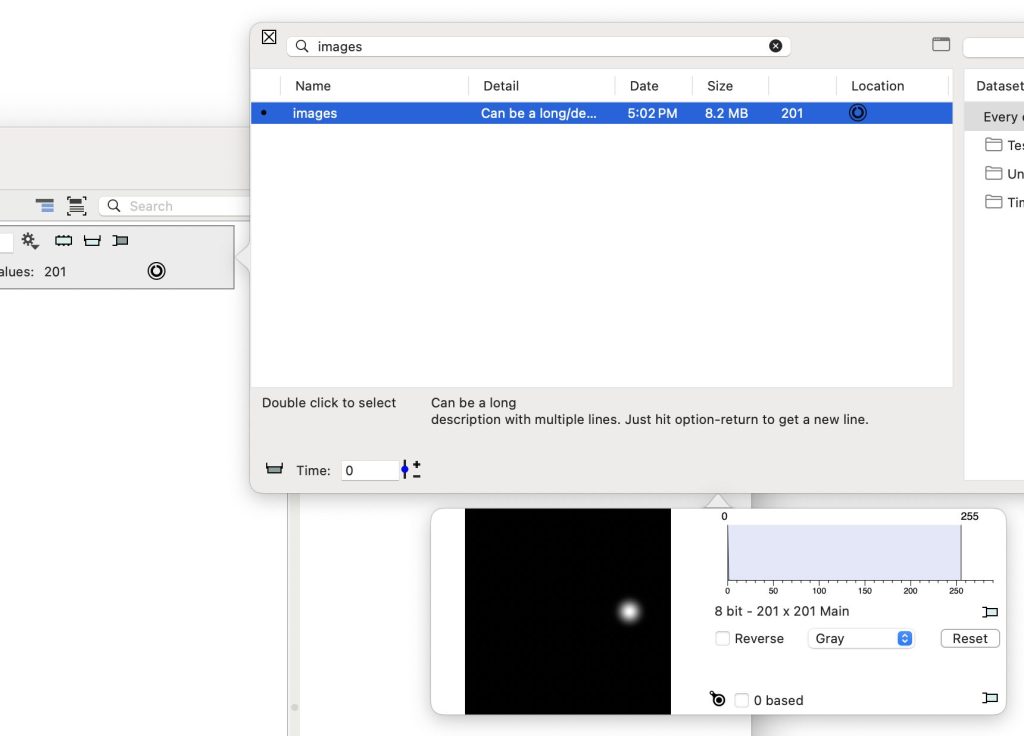
Selecting a snapshot is different than the standard way to select a file. One way to describe the difference is that the snapshots are in a database instead of a file system. You find them by querying the list of snapshots that exist on your machine. The following screenshot shows what happens when you click on the side panel for a snapshot. It shows the list of all Image variables that are on your machine. You can use the search field at the top to hone in a file. Note that there is a built in variable monitor at the bottom that allows you to get a preview of the dataset without selecting.
If you don’t have a snapshot variable already in the object list, use the File entry in the toolbar to create a blank snapshot entry. Then you can select it.
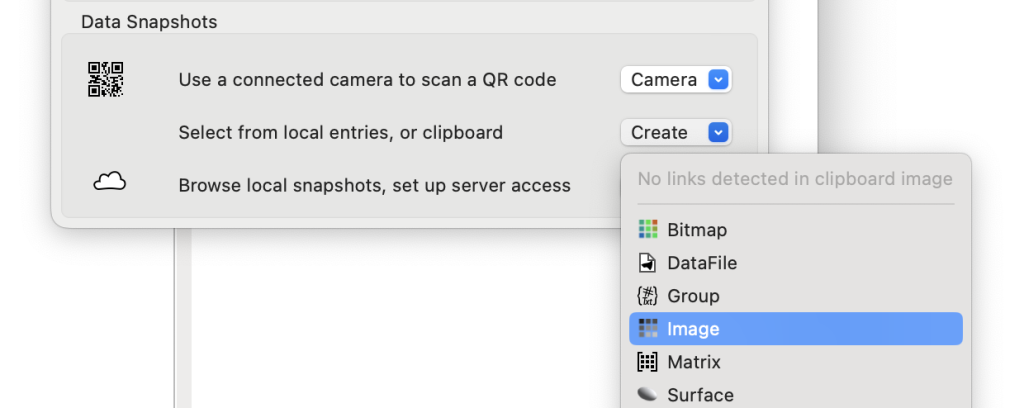
You can also drag the snapshot from one ImageTank file into another to take a copy. There are several other ways to select and share Snapshot entries that will be described elsewhere. One of those methods is hinted at in the above screen shot, tihs is described a little bit further down on this page.
Host on S3
Set up a Bucket
To store Snapshots remotely, you need an S3 compatible storage solution. S3 was created by AWS and you can set this up through them, but there are a number of other providers, and one recommendation is to use Backblaze. They have an S3 compatible storage, in Dec 8th 2025 the price was $6/TB/Month. There is a fee for downloads if they exceed three times what you are storing. There is a higher tear (15$/month) with no caps and higher speeds. See this link on Backblaze.
Note that ImageTank will cache your downloads so extra download costs are likely not going to be a problem if you are using for collaboration.
In addition, a lot of storage systems allow you to access data through the S3 protocol, like NetApp. That means that if you are at a university or a research institution changes are that they can set it up for you. That has the added benefit of staying on premises and not having to depend on a third party provider.
Storing Snapshots in the Cloud
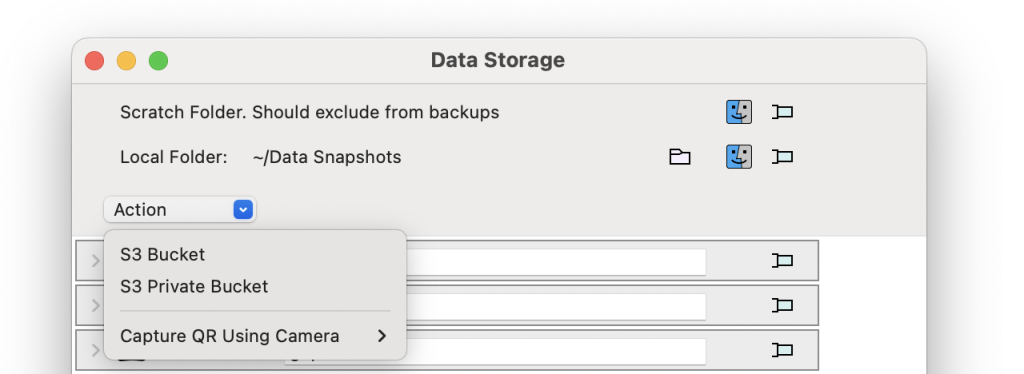
Snapshots are managed by ImageTank, and are stored in one of three places. The first is the scratch folder. This is stored inside the Library folder in your home directory. A recommendation is to exclude the cache directory from your daily backups. Ideally what should be in the cache is either also on a server that you have access to or very temporary.
The second is the Local folder. You control what files go in and you handle the removal.
The third is cloud storage that you have access to. You can have multiple buckets.
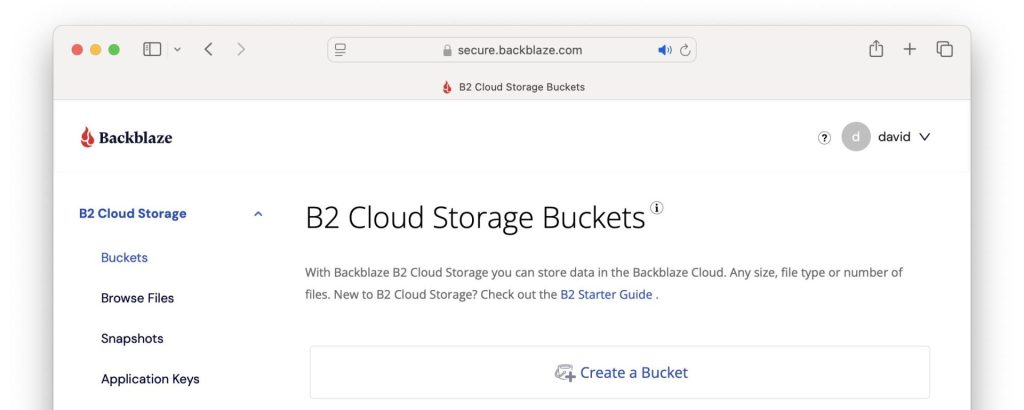
If you have access to an S3 bucket, skip a little bit ahead. If you do not have a S3 bucket it is easy to set it up on Backblaze.com. This is completely separate from ImageTank, and likely other companies that support S3 buckets have a similar UI setup. Backblaze is reasonably priced for individual use, and is great for off-site backups. The following screenshots show you the steps (recorded in Dec ’24) to set up a S3 bucket on Backblaze.
Once you have an account, you get the following page to set up S3 buckets. Click on the “Create a Bucket” button
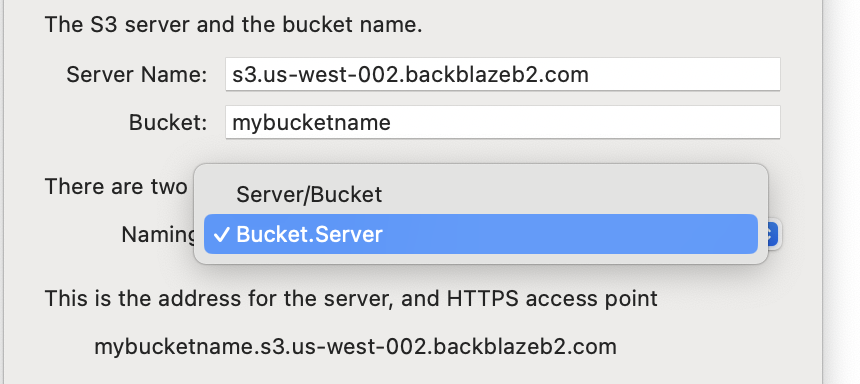
Next you set the bucket name and settings. Note that the buckets will be called BucketName.s3.us-west-002.backblazeb2.com. The big decision is to select between Private and Public option.
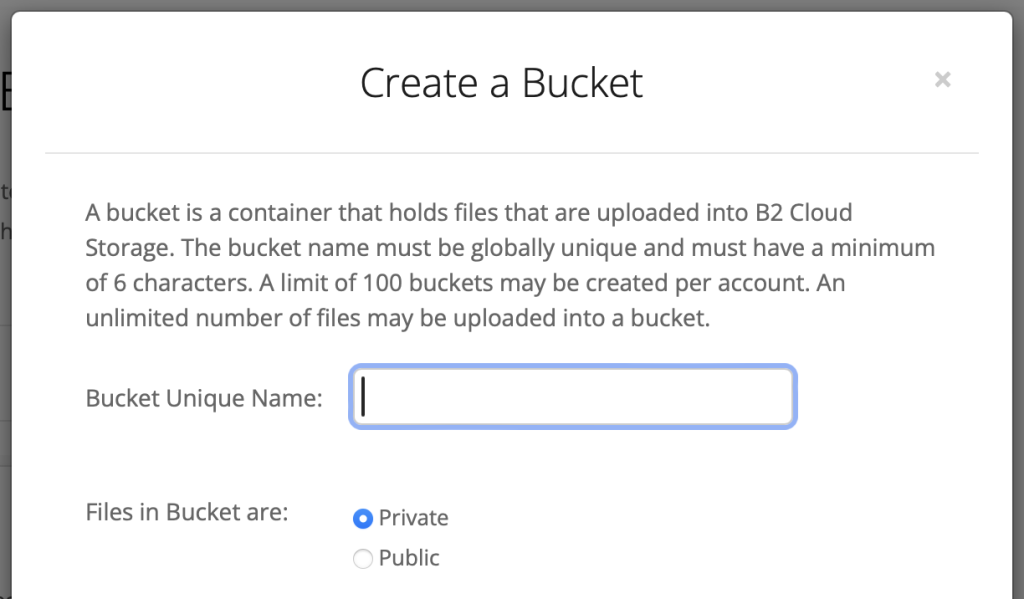
The difference is that Private means that you need to have an access code to read and write to the bucket. The ‘Public’ option means that you need access code to write to the bucket, but not to read from it.
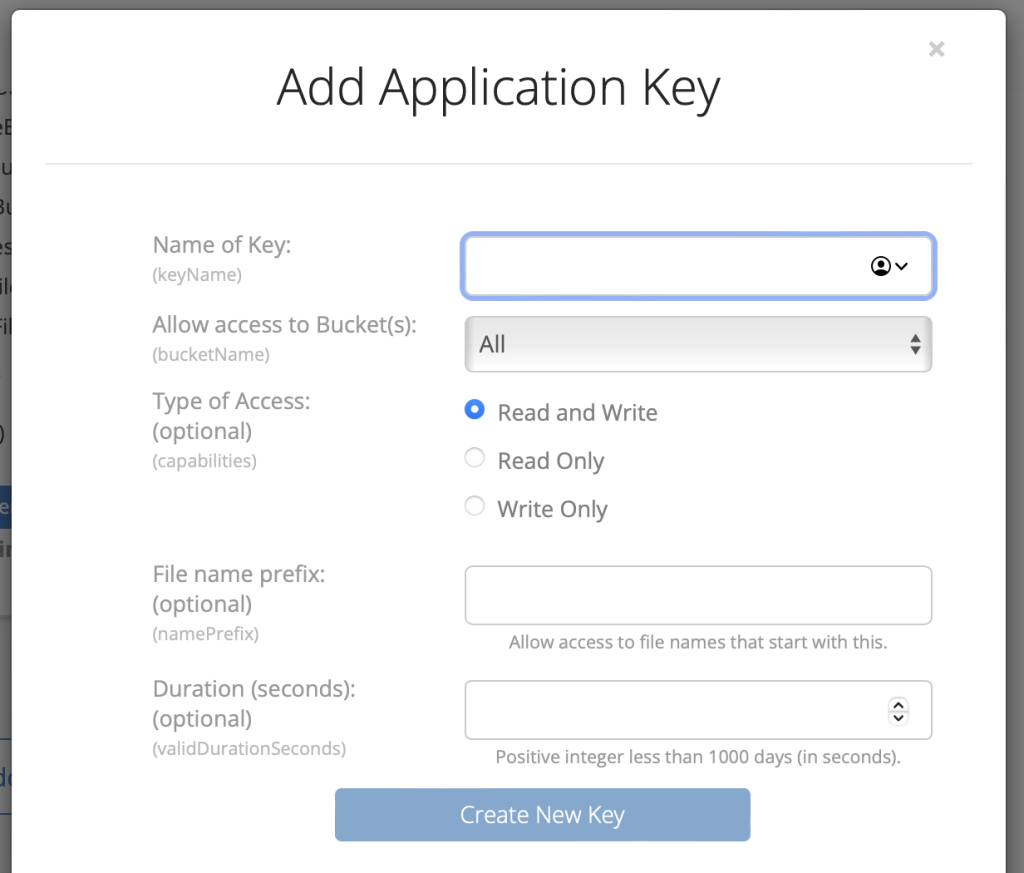
Once you have the bucket, you need to set up an access key, which Backblaze calls “Application Key”. On the left side of the window, select that tab. You have to set up a Master key once, but then click on the button to add a new application key.
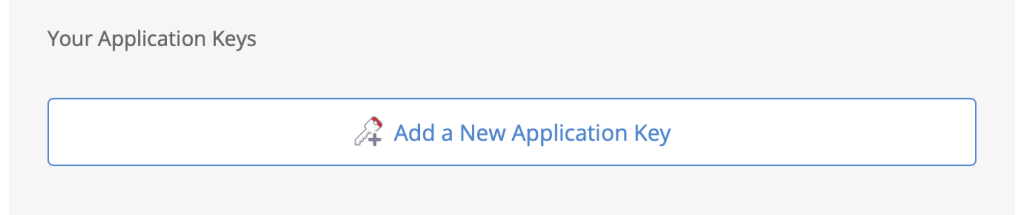
Give the key a name, select the bucket you want to get an access key for, and then select the Read and Write, even for the Public bucket. Leave the other fields blank.
If you are sharing within a group, you can use the private bucket. If you want to send snapshots to someone outside the group, essentially a “anyone with the link” type of share use a Public bucket. Select ‘S3 Bucket’
What you get is a setting window
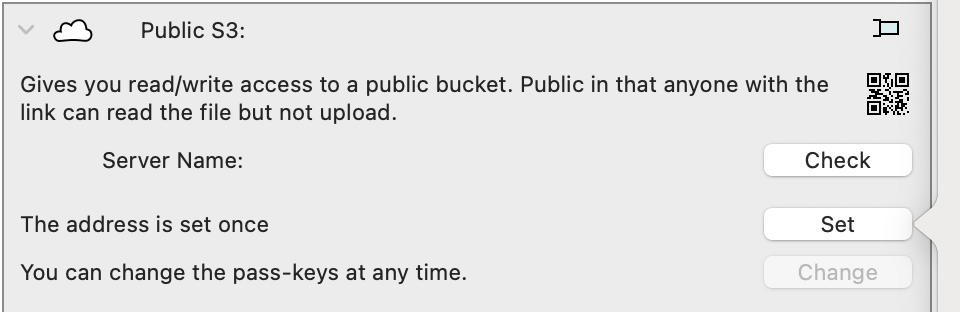
There is a setup panel. It explains the steps needed. Note that for Backblaze their naming convention is bucket.server so you need to select that. Other implementations ue server/bucket. Click on the “Check” button to finialize the setup. Once you have you can not change the settings. If the information changes click the Change button.
Now you have your own S3 bucket, ready to be used to share Snapshots. If you are in a snapshot entry, use the Action menu and select the bucket you want to upload it to.
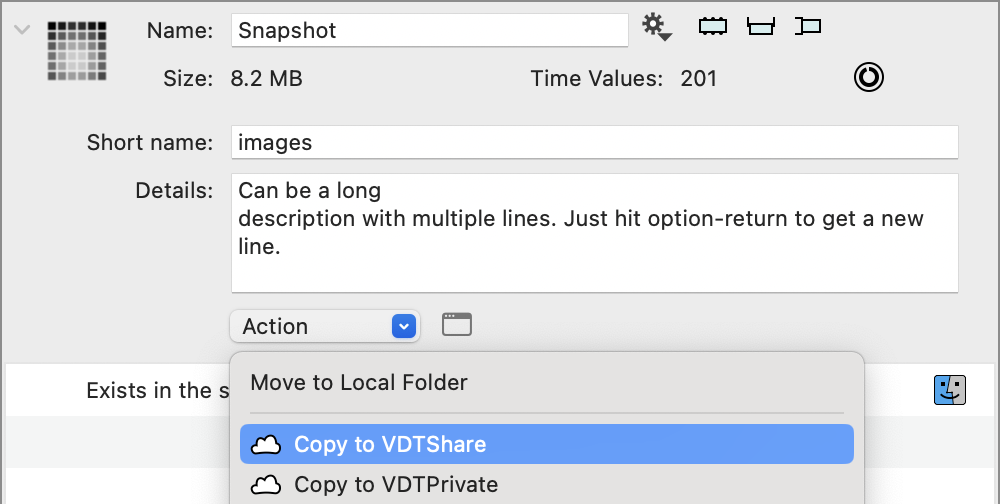
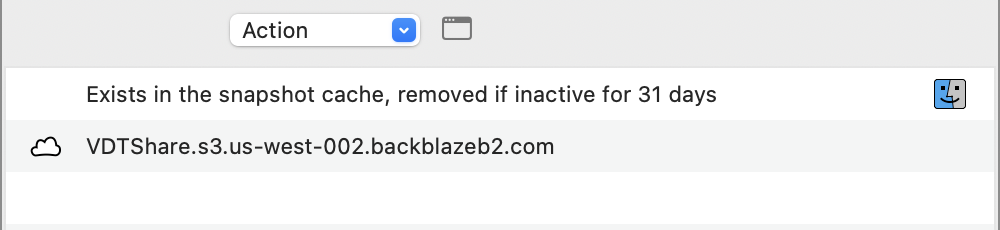
Once it is uploaded you can see in the location list that it is now in the S3 bucket.
Sharing an S3 bucket
You can share this setup. Note that your VDT userID (the e-mail on your account) is registered as the owner of the bucket in the directory server, and some actions on the registration server are limited to the user that set up the bucket. However, and very importantly, the S3 application key gives you read/write access to the bucket that can be used in other S3 administrative tools.
You can quickly share the setting through a QR code. Click on the small QR code icon to get a pop-up window with the information encoded into a QR.
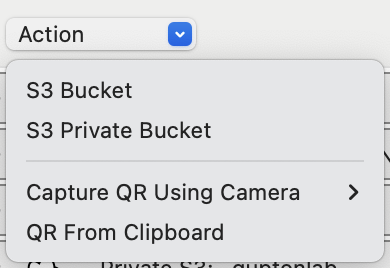
You can use this in two ways, first you can use the camera on the recipient computer to capture the QR code off the screen. This works if the recipient has a web cam. You can also take a screenshot of the pop-up screen and send it by text or e-mail to the recipient. They copy the image and use the action menu. If ImageTank notices a bitmap in the clipboard that has a valid QR code it adds the “QR From Clipboard” entry to the menu.
Sharing a Snapshot
The benefit of uploading snapshots to the cloud is two fold. First you don’t have to store them long term on your own computer. Second is that you can share them will collaborators or send anyone a link to the file and they can download them. There are a few ways to do this:
In an ImageTank file
If you send over the ImageTank file that uses a snapshot to someone, ImageTank will check if there is a local copy of the data file available on the machine, and if not will download it from the cloud automatically. This assumes that the S3 Bucket is world readable or the reciepient has access to the same Private S3 bucket. Note that World readable does not mean browseable by everyone. This is something you set up when you create the keys for the S3.
Clickable link
You can also send a link to the data directly.
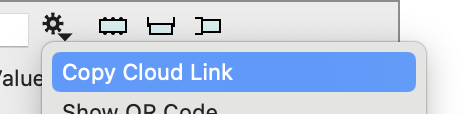
Use the gear menu and select the ‘Copy Cloud Link’. this copies a link like itank://data/Image:2fbebebde5adee7bef145e162fbc3dabca2672196be6cc9f7e536b4680381694 If you click on this link in Safari you get a promt to have ImageTank open it, just like when you click on a Zoom link. What ImageTank does is to open up a window with the snapshot. The snapshot is automatically downloaded. Since this is a sharing site, the above link will work for everyone.
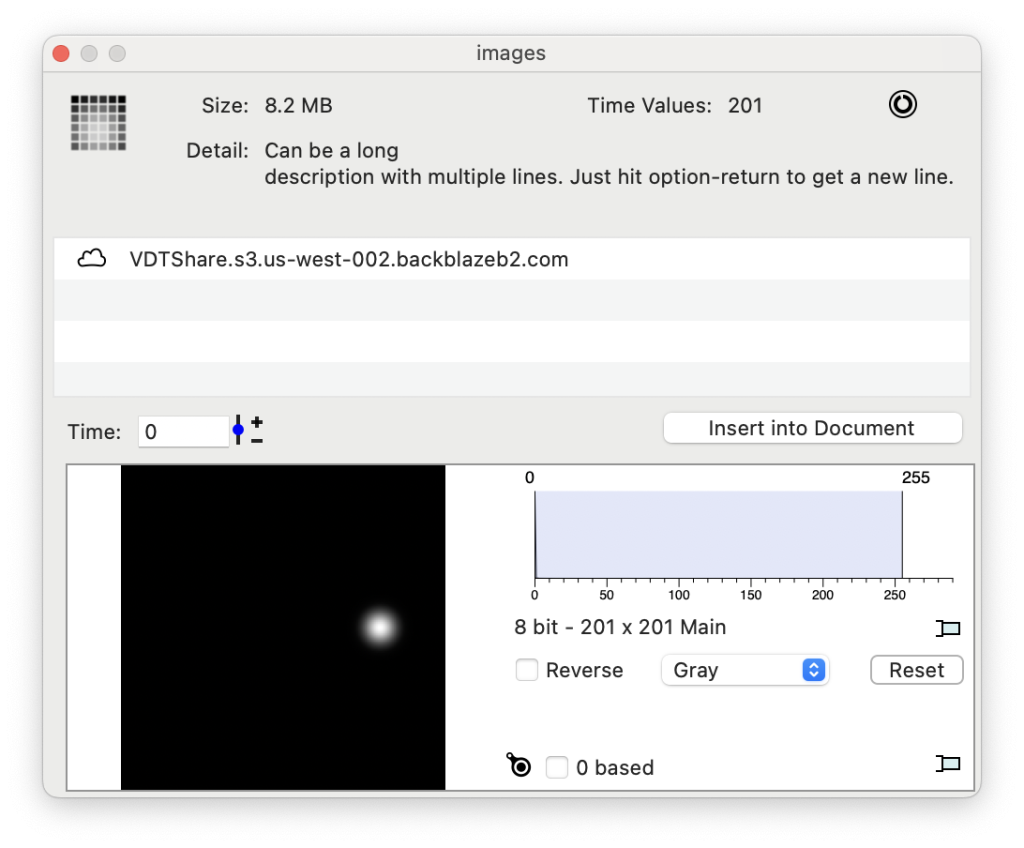
You can also copy the text of the link
itank://data/Image:2fbebebde5adee7bef145e162fbc3dabca2672196be6cc9f7e536b4680381694and paste it into an ImageTank document, ImageTank will detect that you are pasting in a URL.
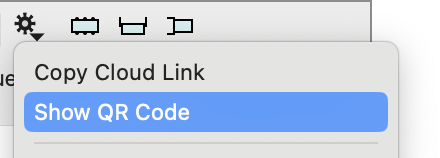
QR Code
A snassier way is to use a QR code. You can have ImageTank bring up a QR code that encodes the above link.
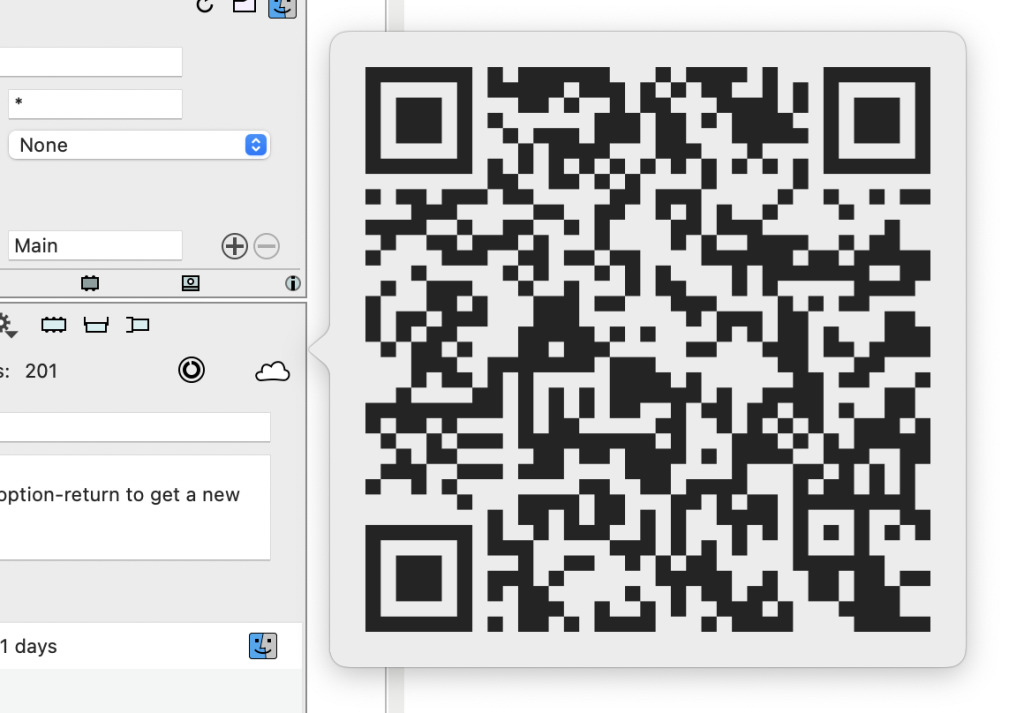
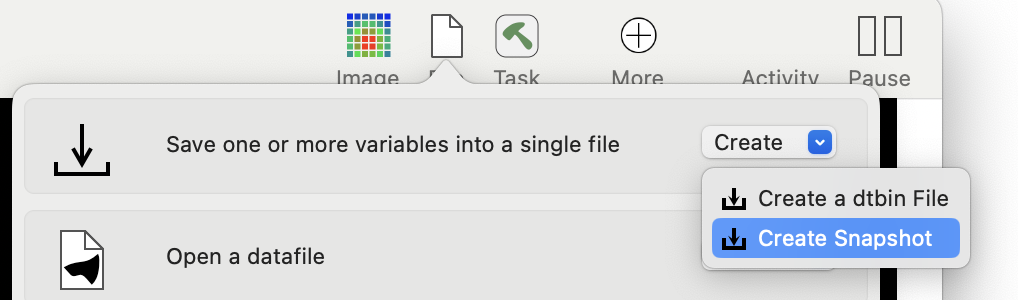
There are several ways to use this QR code. One is that you can take a screengrab of the QR and paste it into an ImageTank document. For example if you show this QR code in a Zoom call. You can also go into the File menu in the toolbar and use the Create menu. It detects that there is a picture of a Snapshot object in the clipboard (you can have more than one).
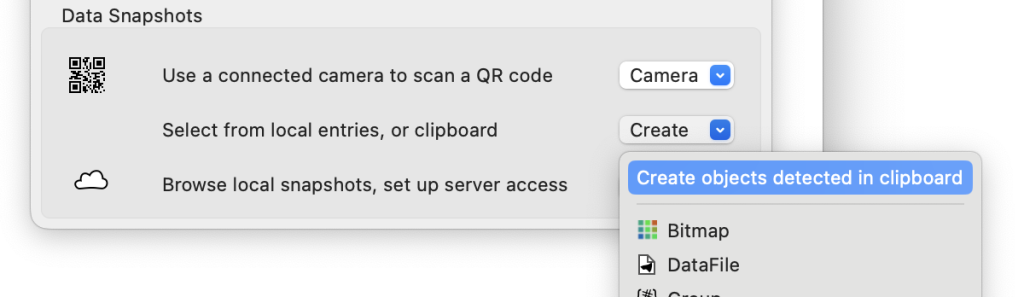
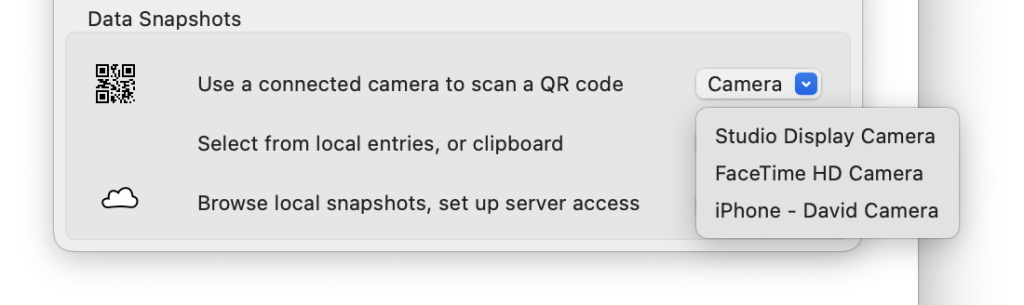
Finally, you can use that same window to use the camera to scan in the QR code. For anyone that has an iPhone you can use the Continuity Camera functionality as an external camera for your Mac. Point it to the QR code and as soon as ImageTank detects a valid QR code it will insert the object into the variable list.
Searching Connections
When you use a snapshot in an ImageTank file, you can view that as a connection between the file and data. This connection is in two directions. The obvious one is that the snapshot shows up as a variable object. The not so obvious is the other direction. If you have a snapshot you can find all of the ImageTank files that use that snapshot.
In the snapshot entry, go into the Action menu and select the search entry.
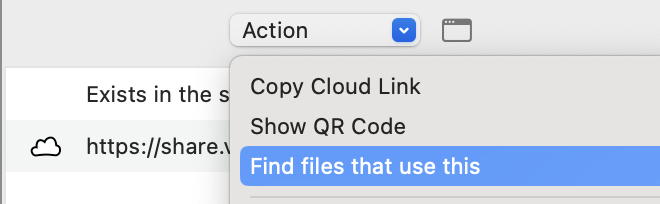
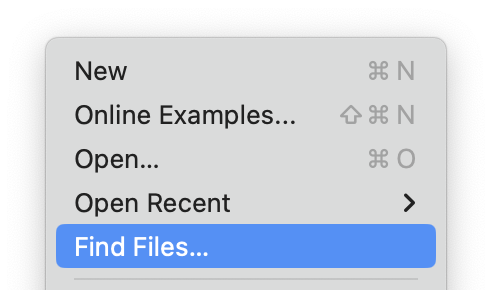
This brings up the “Find Files…” window, the one that is available from the File menu.
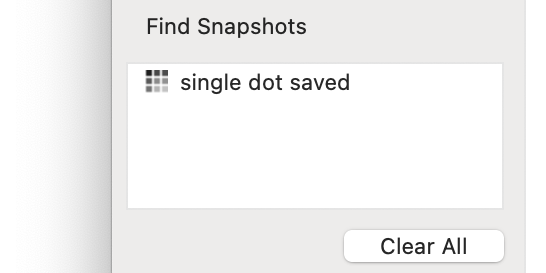
It enables a hidden feature – to filter based on snapshots.
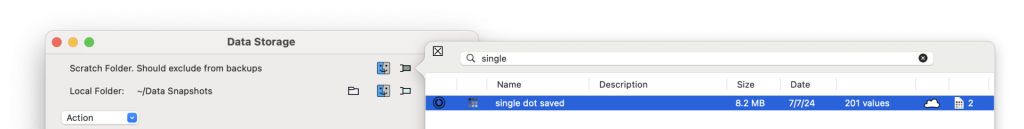
You can also see file information in the Data Storage window. Go to the snapshot listing for the scratch, local and even remote S3 Buckets. The last column in the table shows how many ImageTank files this snapshot is used in. You can click on the icon to go to the search window, or use the context menu to open that file directly.
Guidance on Snapshots
Snapshots are still under development, so laying out rules on how they should be used is a little premature. Here are some ways that work, some that can lead to issues and other thoughts.
Standard ways to store files in folders and sub-folders have problems have issues that Snapshots are meant to address. The big issue is that it is really hard to share data using this approach. Progams that hard code in names need the file structure to be exactly the same, or at least relative to some kind of project directory. Sending such a cluster of files involves a combo of zip-ing, drop box or upload sites, and then careful checking. And that needs to be done every time the calculation has to be re-visited.
- Try to put a certain experiment (e.g. imaging) into a single snapshot. If the experimential data is just a single stack and/or time sequence of images (2,3,4 or 5 “dimensions”) you can put that into a single object in ImageTank. That object could be fairly large and 20GB is pretty common. If the data is more complicated such as a time series with a few reference images and a writeup/documentation you can use a Data File snapshot. You can drag variables and files into the list and then hit Save to create the dataset.
- For the short name you don’t have to put a lot of details, that is what the details field is for. In the details you can put a fair amount of text. Put there keywords that you can use in the search field. For example the name of a project, parameters used, who created it etc. You can add new lines (shift-return) to format this.
- The S3 snapshots are very handy for collaboration. It splits the code (ImageTank file) and the data. You can even send the ImageTank files by e-mail or text since they aren’t that big. Having the data handled automatically removes the worry of getting the data set up and making sure it is exactly what was used by the sender. Since the ID is a checksum of the data it either uses the exact same data or can’t connect.
- If you set up a publicly accessible S3 bucket, anyone needs the unique 64 character checksum. This is not something one can brute force, and as long as the S3 bucket doesn’t allow file listing on a public site (that should by default be off) just knowing the website location is not enough. This allows you to send scripts to people outside your research group. They won’t be able to browse the content of the directory. You can of course set up both a private and “public” S3 and put a file on both.